From better prompts to better operators: the road ahead for AI proficiency measurement
From better prompts to better operators: the road ahead for AI proficiency measurement

Marc Gerard
·
Product Lead

TLDR
- The 70-20-10 learning model matters because most learning happens through work and peers, not formal training alone. - Tracking AI training and adoption is easy; measuring whether employees actually improve in real work is much harder. - Nebuly turns anonymized AI interactions into an AI Proficiency Score and Novice-to-Expert groups, so capability can be tracked over time. - AI proficiency goes beyond prompt quality. Anthropic's 4D framework covers Delegation, Description, Discernment, and Diligence. - Today, Nebuly goes deepest on Description. The roadmap expands across all 4D dimensions, then into context management, tools, workflows, reusable skills, and agent orchestration.
Two employees use the same AI assistant every day. Both completed the same training. Both appear as active users in the adoption dashboard.
One gives a vague instruction, spends several turns correcting the output, and still rewrites most of it manually. The other explains the goal, provides the right context, defines what good looks like, and gets to a useful result quickly.
Most company systems would treat these employees as equally successful AI users. They are not.
HR and L&D teams can train employees, track attendance, monitor course completion, and run assessments. The investment is already substantial. In Wharton Human-AI Research and GBK Collective's 2025 enterprise study of 801 decision-makers, nearly two-thirds of enterprises budgeted $5M or more for GenAI, with employee training accounting for 16% of GenAI budgets on average. Yet even among organizations measuring GenAI ROI, only 42% track changes in employee performance after training.
That leaves a much harder question:
Did employees actually get better at using AI in their day-to-day work?
Course completion shows exposure. A quiz shows recall. Neither shows whether employees now frame tasks more clearly, provide better context, work more effectively with AI, or reach better outcomes.
This is the gap Nebuly's AI Proficiency module is designed to close. By analyzing anonymized traces of real AI interactions and tasks, Nebuly measures how AI capability shows up in actual work.
The shift is simple: from measuring AI training and adoption to measuring AI behavior and improvement.
What we measure today
Nebuly's current AI Proficiency methodology looks at how employees work with AI in real situations, rather than how they performed in a classroom.
It looks broadly at behaviors such as how clearly a user frames a task, whether they provide useful context, how effectively they guide the interaction, and whether the conversation moves toward a useful outcome.
The main KPI is the AI Proficiency Score. It is complemented by user proficiency groups, from Novice to Expert.
Together, these signals make it possible to see how AI capability is changing across the organization: by user, team, department, and over time.
This helps companies answer practical questions:
Are employees actually improving after AI training?
Where is additional enablement or coaching needed?
Which teams are developing stronger AI working practices?
Are proficiency levels improving over 30, 60, or 90 days?
You can read more about the current methodology in the Nebuly AI Proficiency documentation.
Measuring applied learning, not just training
AI proficiency is ultimately a behavior-change problem.
Most learning systems can show who attended training, completed a course, or passed an assessment. What is harder to see is whether people actually changed how they work.
AI makes that behavior more observable. Prompts, follow-ups, sessions, tasks, and interaction patterns leave a trace of how employees are applying what they know in practice.
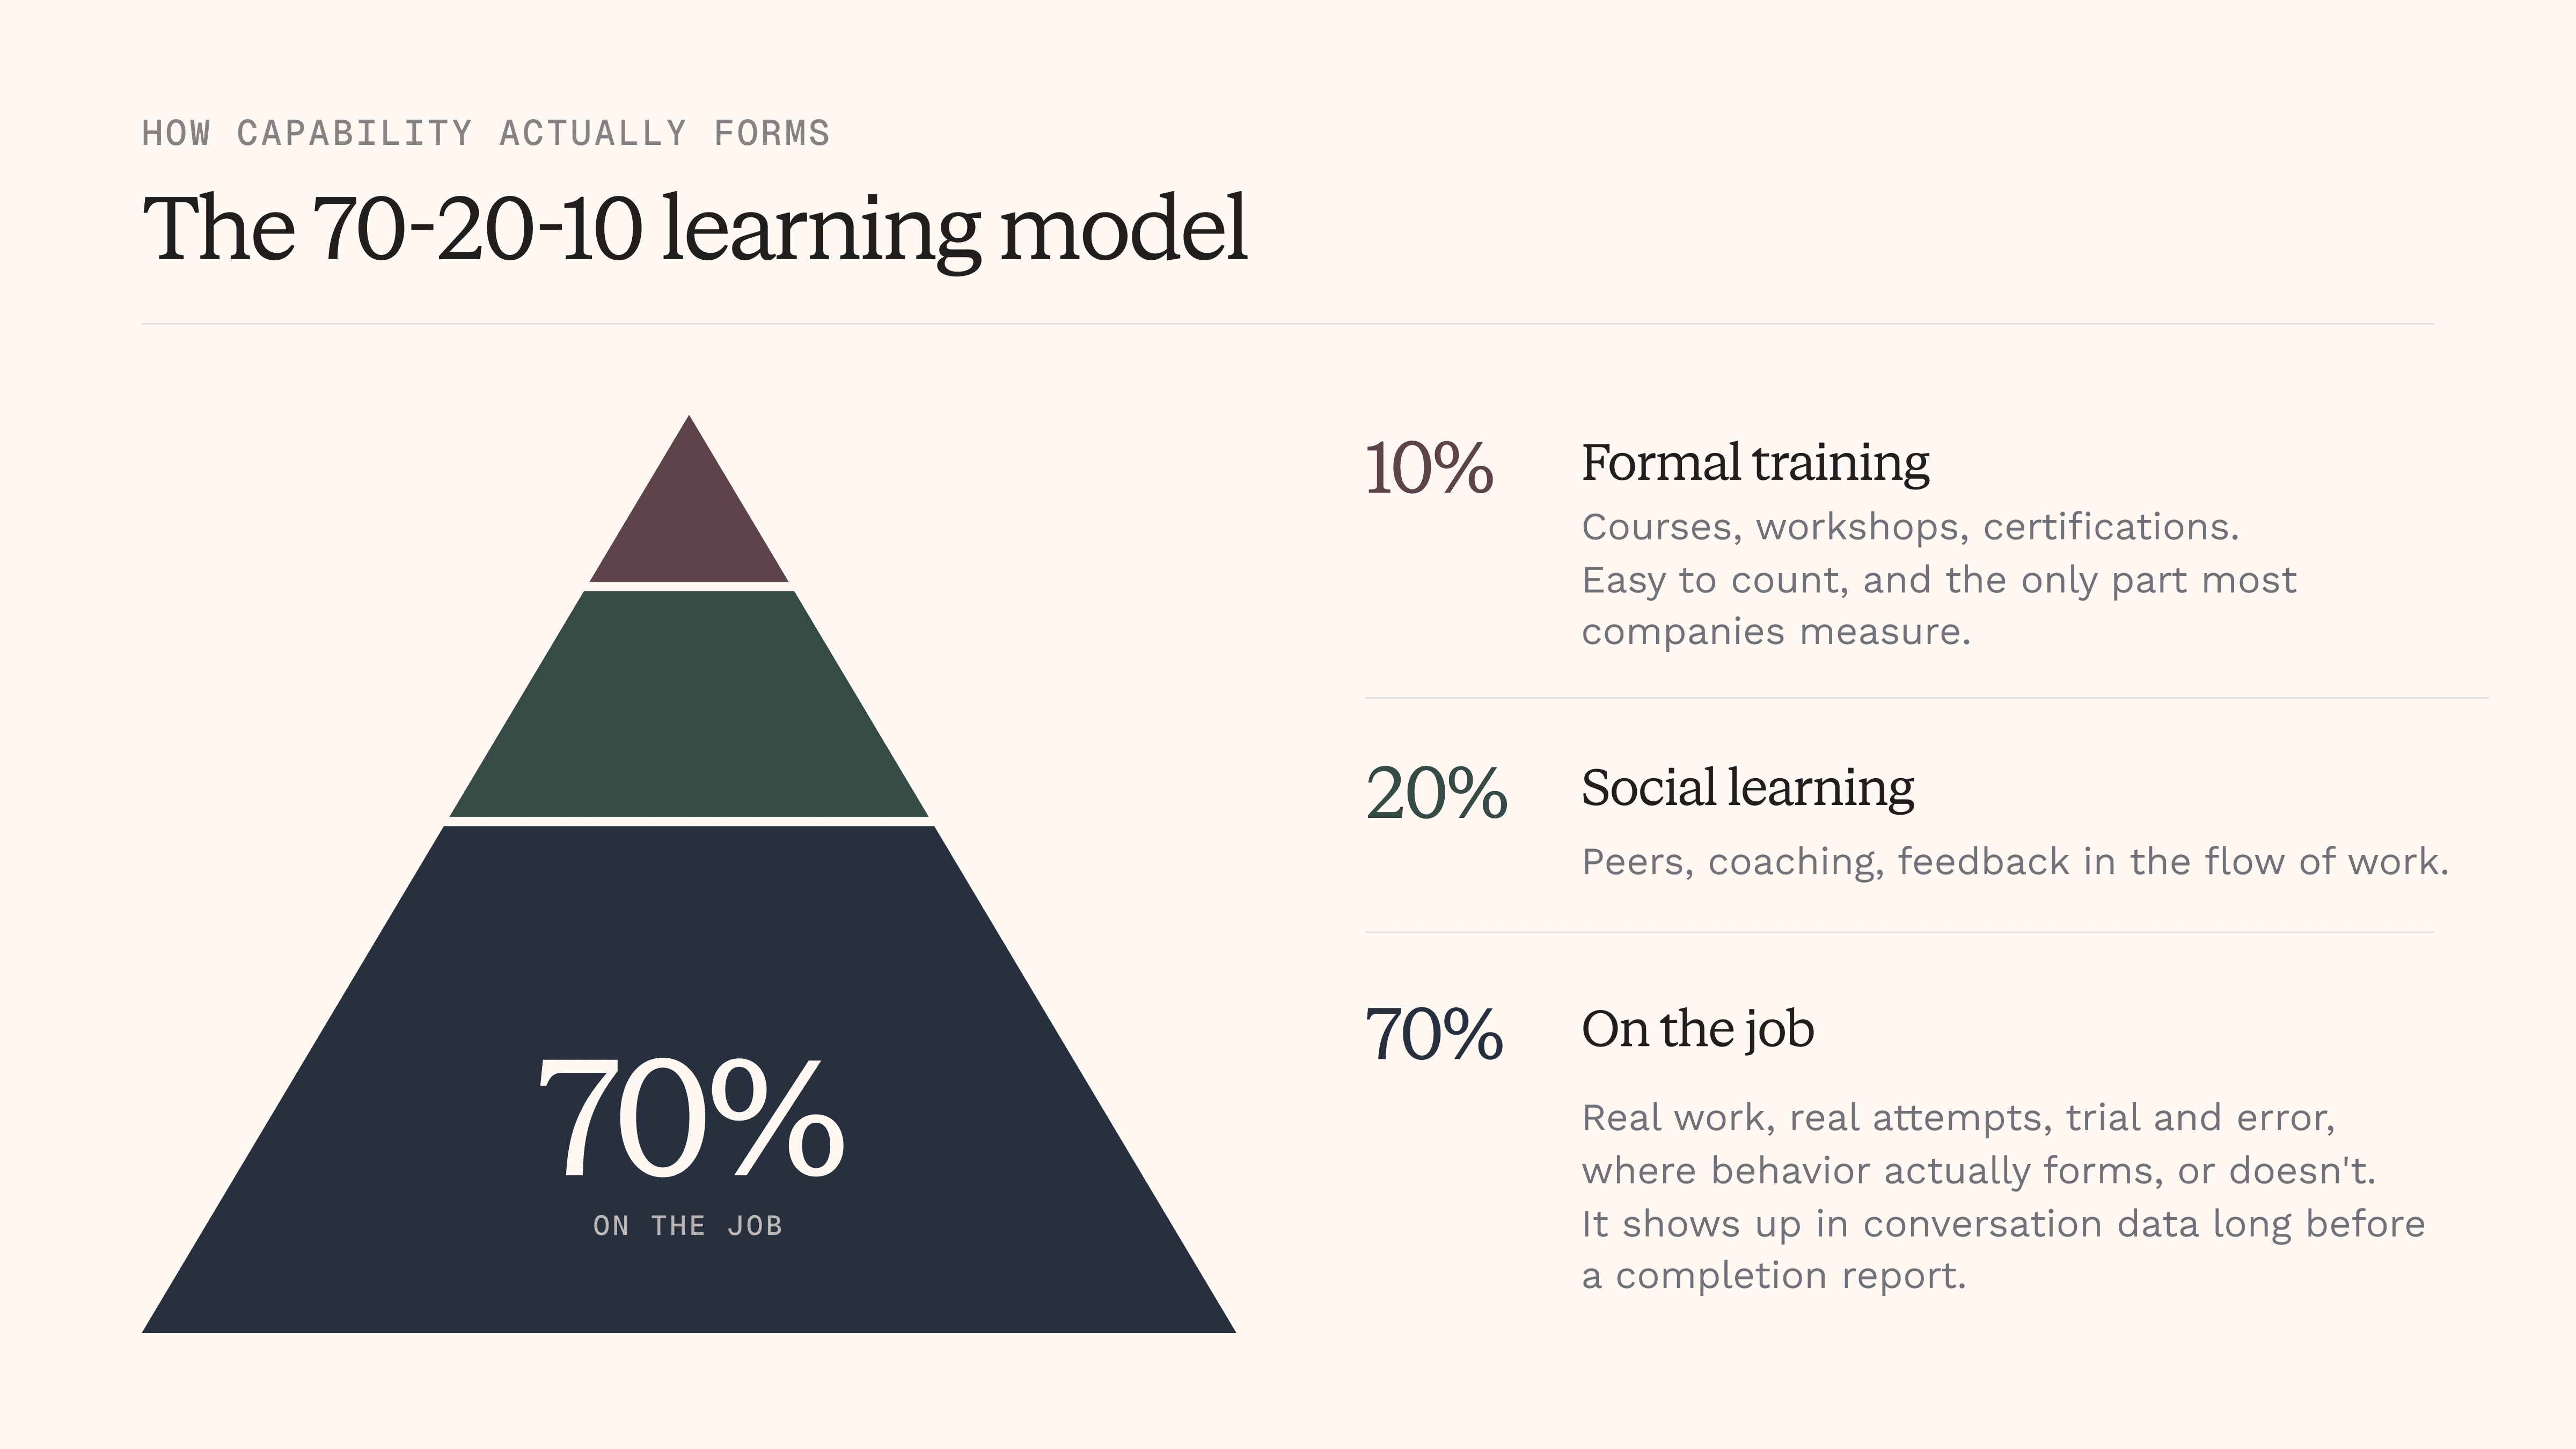
This connects naturally to the 70-20-10 learning model, which grew out of the Center for Creative Leadership’s Lessons of Experience research and was later codified by Michael Lombardo and Robert Eichinger. The model emphasizes that much development happens through on-the-job experience and learning from others, not only formal training.
By tracking real AI behavior over time, companies can see whether capability is improving regardless of where the learning came from—and whether that improvement is spreading across the organization.
From prompt quality to the 4Ds of AI fluency
Prompt quality is a useful starting point, but it captures only part of how well someone works with AI. A broader view comes from Anthropic's 4D AI Fluency Framework, developed by Rick Dakan and Joseph Feller, which describes four connected capabilities:
Delegation — deciding what work should be done by a human, what should be done by AI, and how the work should be divided.
Description — communicating goals, context, constraints, and expectations effectively to the AI.
Discernment — critically evaluating AI outputs, identifying missing context, checking important claims, and challenging weak reasoning.
Diligence — using AI responsibly, transparently, safely, and with appropriate accountability.
Nebuly's model today goes deepest on Description, where many of the most observable interaction signals live: how clearly a user explains the task, gives context, sets expectations, and guides the model.
But Description is only one part of AI fluency. Anthropic's AI Fluency Index reinforces this point: clear instructions do not necessarily mean that a user is also strong at delegation, critical evaluation, or responsible use.
That is why we see AI Proficiency as an evolving measurement system, not a static prompt score.
The roadmap: measure all four dimensions of AI fluency
The next stage of AI Proficiency will move beyond evaluating individual prompts and toward understanding how a user behaves across the full interaction.
Delegation. We want to understand whether users make good decisions about how to use AI: what to delegate, how to break work into steps, which interaction mode to use, and where human judgment should remain in the loop.
Description. We will deepen the area we already measure today. Beyond task clarity and context, this can include examples, success criteria, audience definition, interaction style, and richer context management.
Discernment. Strong AI users do not simply accept polished answers. They verify, challenge, refine, and notice what is missing. We plan to measure signals such as whether users question reasoning, validate important facts, give corrective feedback, and improve weak outputs.
Diligence. AI fluency also includes responsible use. Where it can be observed safely and reliably, the model can account for behaviors around sensitive information, policy compliance, human review, transparency, and the downstream use of AI-generated work.
🧭 The direction is simple: move from "Can this person write a good prompt?" to "Can this person work with AI effectively, critically, and responsibly?"
The best AI users are becoming operators, not just prompters
The way people use AI is changing quickly. Effective AI work is no longer limited to typing a prompt into a chatbot.
Employees increasingly work with reusable skills, files and external context, connected tools, multi-step workflows, and specialized agents. A proficiency model needs to evolve with the work it measures.
Future versions of AI Proficiency will therefore look beyond the 4Ds and add signals such as:
Skills and reusable capabilities — does the user know when to use an existing skill, agent, template, or reusable instruction set? Can they configure repeatable behavior instead of starting from scratch every time?
Context management — does the user provide the right files, sources, instructions, and prior information? Do they know how to give the model enough context without overwhelming it with irrelevant information?
Workflow design — can the user turn a one-off interaction into a reliable multi-step process with checkpoints, iteration, and clear handoffs between human and AI?
Tool usage — does the user know when and how to use browsing, code execution, connected data sources, internal systems, or other tools rather than expecting the language model alone to solve every problem?
Model and agent orchestration — as AI systems become more agentic, can users choose the right model or agent for the task and coordinate multiple capabilities effectively?
These behaviors matter because the strongest AI users are not simply better at prompting. They are better at operating AI systems.
Nebuly
Nebuly is the ROI platform for enterprise AI. It connects to the AI agents your business runs on, the assistants your customers interact with, and the tools your employees use every day, including Claude, ChatGPT, and Copilot, and translates that activity into business value. How much time is being saved across teams. What revenue your AI is influencing. What adoption and AI proficiency look like in practice, across departments and geographies. If you need clarity on what your AI investment is actually delivering, book a demo.
FAQs
What is the AI Proficiency Score?
The AI Proficiency Score is Nebuly's main KPI for measuring how effectively employees work with AI based on anonymized real interactions and tasks, rather than on training completion alone. It is complemented by user proficiency groups from Novice to Expert, making it easier to track improvement across people, teams, and time.
How is AI proficiency different from AI adoption?
Adoption tells you whether people use AI—for example, whether they have access or are active users. Proficiency looks at how effectively they use it. Two employees can have the same level of adoption while showing very different levels of capability in real work.
Why measure proficiency after AI training?
Training completion shows that someone was exposed to the material. It does not show whether their behavior changed. By looking at real AI interactions after training, companies can see whether employees are actually improving and where more support is needed.
How does the 4D AI Fluency Framework relate to Nebuly's methodology?
Nebuly's current methodology goes deepest on Description—how clearly users communicate goals, context, constraints, and expectations. The roadmap is to broaden the model across Delegation, Discernment, and Diligence as well, so proficiency reflects the full way people work with AI.
What will AI Proficiency measure in the future?
Beyond the 4Ds, we expect the model to incorporate broader AI operating skills such as context management, reusable skills, tool usage, workflow design, and model or agent orchestration.


Stay up to date on what we're learning, building, and seeing as enterprise teams deploy and measure AI agents in production.